vllm.ai
vllm.ai is Blog + benchmarks. It is ranked #123 on the Dev Radar, in AI dev tools, first seen 20 days ago and shared in 18 posts (275.6k views).
What vllm.ai says about itself
We make vLLM rollout and the training forward give bitwise identical logprobs on DeepSeek-V4-Flash and Nemotron-3.5-Lightning-30B-A3B (NVFP4), keep 91% of rollo
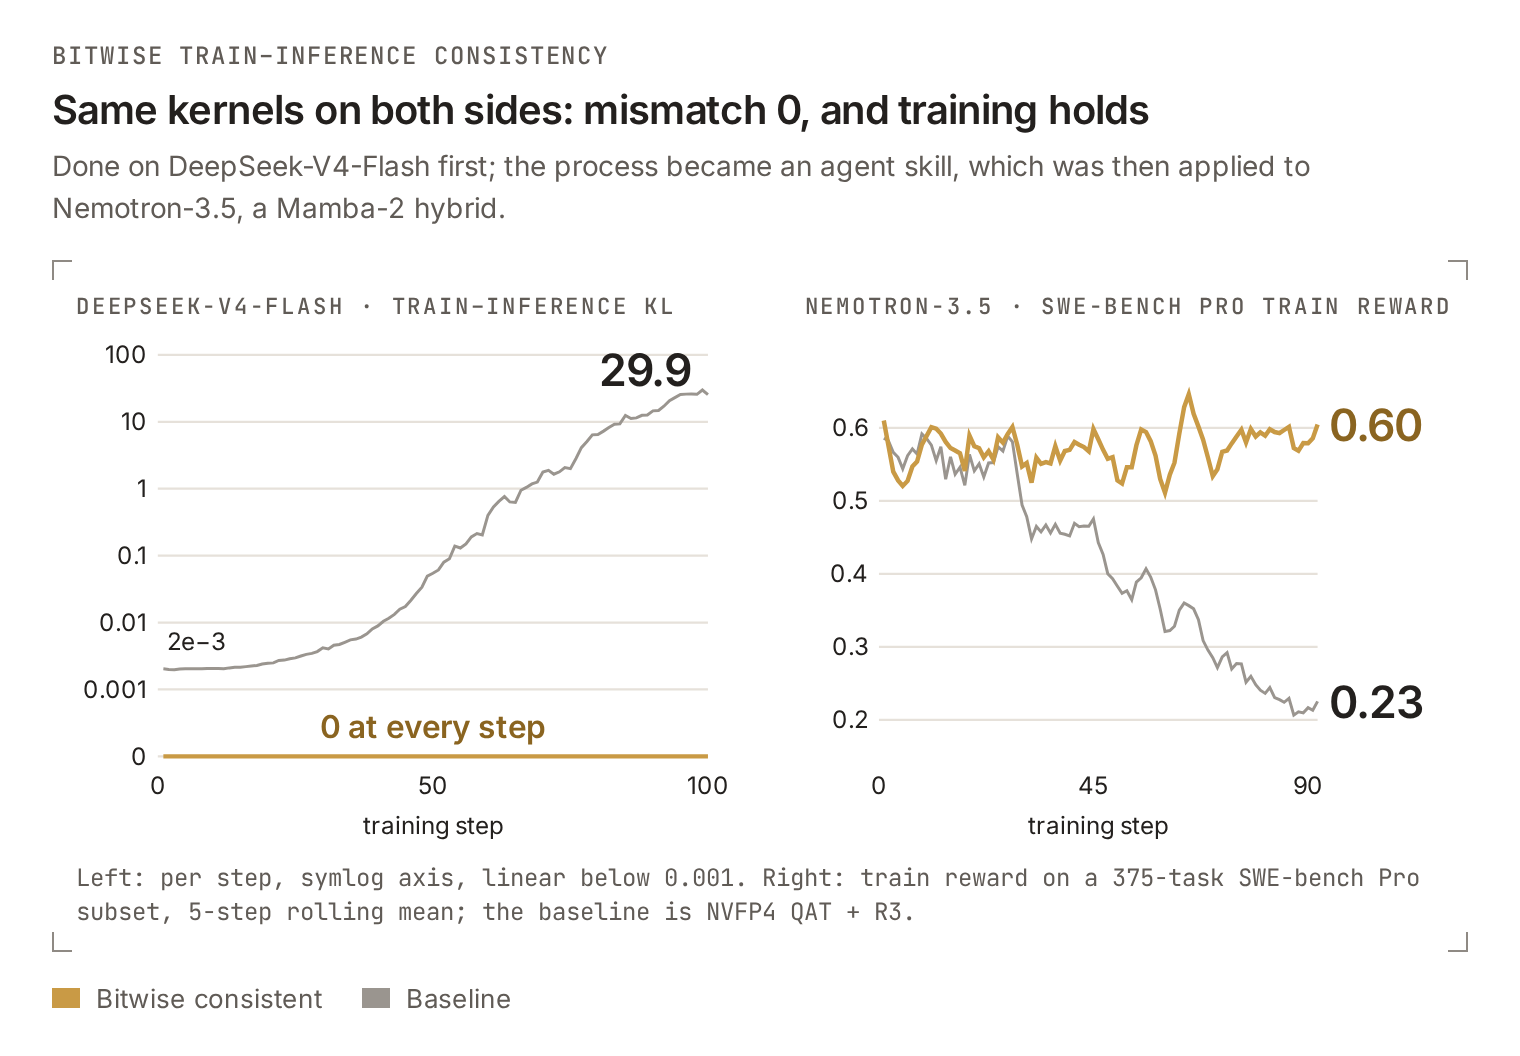
Finish RL Training Faster: Bitwise-Consistent, High-Performance, Agent-Driven | vLLM Blog Menu Theme Finish RL Training Faster: Bitwise-Consistent, High-Performance, Agent-Driven October 14, 2026 35 min read Yan Bai (NVIDIA DevTech), Ao Shen (Inferact) # reinforcement-learning # deepseek Table of Contents TL;DR Problem : inference-side optimizations in high-performance RL change the numerics, so training optimizes a policy other than the one that sampled. On DeepSeek-V4-Flash, the high-performance baseline's train-inference KL rose from 2e-3 to 29.9 while reward fell back. Approach : the training forward calls vLLM's inference kernels…
What people said about vllm.ai on X
🎉 Congrats @deepseek_ai on DeepSeek-V4.1-Flash-1017! Better scores and shorter outputs make it a great fit for long agent loops. Making each step fast is the serving side's job. On DeepSeek-V4.1-Flash, vLLM delivers 1.3B tokens per dollar TCO on SemiAnalysis AgentX: 830K tok/s per GPU (cached + input + output) at…
— @vllm_project, 13 days ago · 612 likes · see the post
Quantization is easy. Fast quantization kernels for every format × every GPU × every workload are not. Today we're open-sourcing Humming with Ant Group: one kernel library for all of it — up to 5x kernel speedups, +14–43% E2E MoE throughput. Blog + benchmarks: https://vllm.ai/blog/2026-10-21-humming
— @vllm_project, 9 days ago · 479 likes · see the post
Coding agents are optimizing NVIDIA CUDA kernels. For Kimi K3 in @vllm_project, we used agent-assisted development to build a unified CuTe DSL decode path that delivers 842 tokens/sec at batch 1 on NVIDIA GB300 NVL72, backed by kernel tests, model evaluations, and reproducible benchmarks. Learn more ⤵️
— @NVIDIAAIInfra, 12 days ago · 399 likes · see the post
Alternatives to vllm.ai
- goo.gle — Officially in beta, the AppFunctions API is opening up powerful new ways to integrate your functionality.
- Kimi AI with K3.1 Pro — Try Kimi K3.1 Pro to tackle complex coding projects, build 3D models, conduct financial research, and take on more…
- Agents in flight — Give it a try
- Baseten — This session is our most in-demand yet. See you there
- project-maya — Checkout Maya
- deepinfer — You gotta love Deepseek. This is awesome stuff!
vllm.ai in numbers
- Rank on the Dev Radar: #123 of 8798
- Shared in 18 posts by 8 accounts: @vllm_project, @NVIDIAAIInfra, @keennay, @NFT_Chen
- 275.6k views on those posts
- First seen 20 days ago, last shared 4 days ago
- Pricing seen by AGK Intelligence: not stated
- Market: AI dev tools
FAQ
What is vllm.ai?
Blog + benchmarks It was first shared on X 20 days ago and is ranked #123 on the Dev Radar.
Is vllm.ai free?
Pricing is not stated on the page we read.
Who shared vllm.ai?
8 accounts on X, including @vllm_project, @NVIDIAAIInfra, @keennay, in 18 posts totalling 275.6k views.
Every post is read and classified by AGK Intelligence: what it is, which market it belongs to, and whether the link is a real tool. 31.2k posts from 5k X accounts over the last 21 days, 8.8k tools, 12 markets. New posts are collected several times an hour and the full ranking is recomputed every hour — last update 2026-10-30 20:27 UTC. Full method.