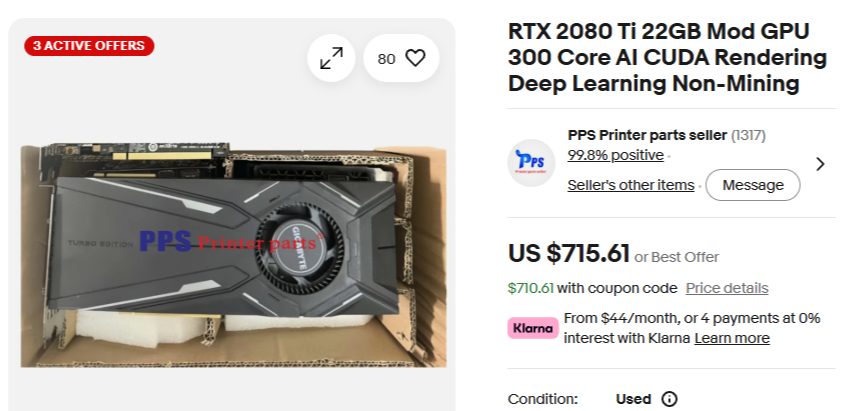
An RTX 2080 Ti from 2018. Modded to 22GB.
This is a dev post classified by AGK Intelligence as AI dev tools (a tool drop), kept by the Dev Radar because it carries real work, not commentary.
An RTX 2080 Ti from 2018. Modded to 22GB. Running a 27B local model at a developer-reported 47.5 tps on a code prompt. 👈 👀 Localmaxxers really don’t like retiring hardware. A specialized NInfer fork runs Qwen3.8-27B natively on Windows, targeting the VRAM-modded RTX 2080 TI. The developer’s October 19 measurements ⚡ Standard decode: 27.0 tps 🚀 MTP speculative decoding, code prompt: 47.5 tps 📝 MTP, prose prompt: 28.8 tps That variation matters because speculative decoding’s benefit depends on the workload. The new October 29 release also tackles runtime size. Unused kernels and executio
Posted by David Hendrickson (12.6k followers) 1 h ago · 6 likes · 354 views · view the original post on X. Kept by the Dev Radar as AI dev tools.
More dev work like this
- 花钱找人做SEO诊断,和用开源工具jev-seo一分钟爬完整站,我选后者。 — @bkdgiffug
- 𝗛𝗲𝗿𝗺𝗲𝘀 Agent can read your Google Analytics and answer in plain English. 67 tools,… — @BkashJosi
- 写prompt全凭感觉蒙的人,一天五十个prompt,三次白花,一个月烧掉多少API钱自己算算。 — @bkdgiffug
- 😳什么?!Terminal-Bench狂飙+11.1分!英伟达NVFP4魔改DeepSeek-V4.1-Flash-1017 杀到,Blackwell专属加速,性能成本直接起飞! — @NFT_Chen
- The best world a local AI agent built on each memory class, from 16 GB to 512 GB. One… — @niklaslenz_ai
- Tired of Claude's "Oops my pkill matched my own session"? — @mmastrac
- Well, this is a good sign — @mynameisyahia
- No alerts, but DeepSeek V4.1 Flash with SGLang went from 654K to 1.09M tok/s per GPU in… — @sgl_project
Every post is read and classified by AGK Intelligence: what it is, which market it belongs to, and whether the link is a real tool. 31.2k posts from 5k X accounts over the last 21 days, 8.8k tools, 12 markets. New posts are collected several times an hour and the full ranking is recomputed every hour — last update 2026-10-31 05:36 UTC. Full method.