Insanity? Who has 8x5090s? 🤯 ... this is one for the record books for Local AI!
This is a dev post classified by Jev as Hosting & infra (a tool drop), kept by the Dev Radar because it carries real work, not commentary.
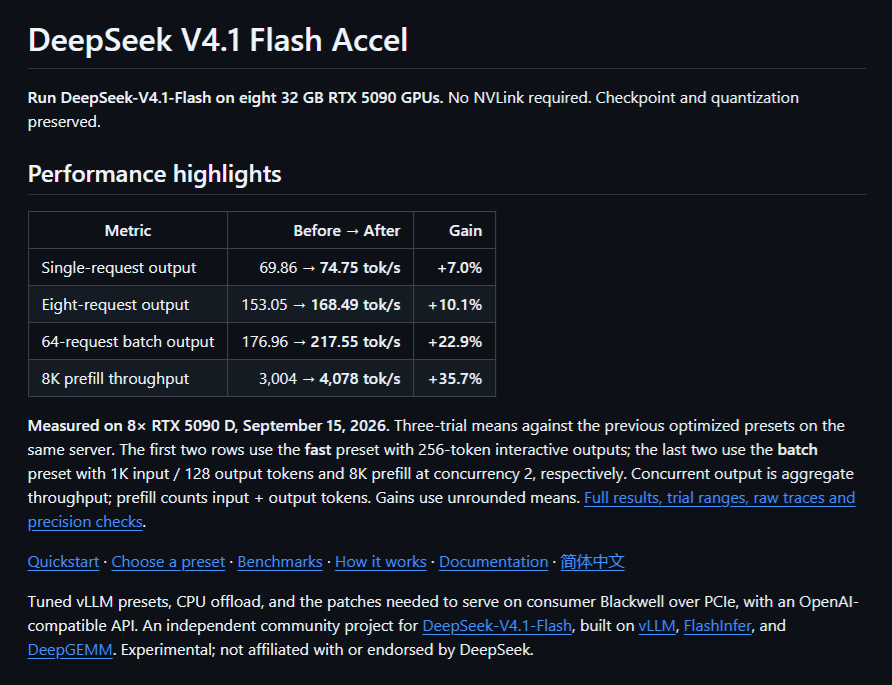
Insanity? Who has 8x5090s? 🤯 ... this is one for the record books for Local AI! A new optimization project has DeepSeek-V4.1-Flash running across 👇 🎮 8× RTX 5090 32GB 👈 👀 🧠 256GB total VRAM 💾 503GiB system RAM 🔗 NO NVLink And the latest results ... ⚡ 74.75 tok/s — single request 🚀 168.49 tok/s — concurrency 8 🔥 217.55 aggregate tok/s — concurrency 64 📚 4,078 tok/s — 8K prefill They didn't shrink the model into some tiny fine-tune. The gains come from the inference stack: ✅ vLLM fixes ✅ CUDA graphs ✅ Expert parallelism ✅ Selective CPU offload ✅ Better movement of MoE experts between RAM + G
Posted by David Hendrickson (11.1k followers) 3 days ago · 29 likes · 5.8k views · view the original post on X. Kept by the Dev Radar as Hosting & infra.
More dev work like this
- To handle bursty, mission-critical workloads without overspending on idle cloud… — @OracleDevs
- Live now: our Inference Engineering Track from AI Engineer World's Fair 2026. — @aiDotEngineer
- gm SF — @AniC_dev
- Last chance: 4 days left to get your ticket to @WeAreDevs! — @Docker
- Accelerating LLM on #AWS Platform! #BigData #Analytics #DataScience #AI #MachineLearning… — @gp_pulipaka
- #MachineLearning with #AmazonSageMaker Cookbook! #BigData #Analytics #DataScience #AI… — @gp_pulipaka
- GSP644: Build a Serverless App with Cloud Run that Creats PDF Files 📄☁️ — @orbitofops
- AWS released six open-source SageMaker agent skills for deploying Hugging Face models.… — @musthaveai
Every post is read and classified by Jev (TypeSafe): what it is, which market it belongs to, and whether the link is a real tool. 15.1k posts from 4.7k X accounts over the last 21 days, 1.7k tools, 12 markets. Collected every 5 minutes, fully re-ranked every hour — last update 2026-09-19 22:52 UTC. Full method.